E mōhio ana ngā tohu ki te tauira i kōwhiria - ka kōwhiria kia whakawātea tētahi ki roto i tōna kupu i reira ka puta ai:
Ka pānui tēnei tauira i te kupu noa, nā reira ka whakakāhoretia ngā tohu ā-waitara. Mō te āhua o te tohu-taihi, ka huri ki tētahi tauira whakamārama pēnei i a Orpheus, Bark rānei.
Ko ngā tohu whakawhiwhinga reo māori. I whakawhiwhia e Qwen3-TTS i tēnei rā; Ka tae mai ētahi atu tauira whakamāramatanga.
Kāore tēnei tauira i te tautoko i ngā tohutohu kāhua — ka huri ki tētahi tauira e mahi ana (hei tauira, Qwen3-TTS).
Ka tautuhia ngā tohutohu ā-ringa (wāhi = tohutohu):
-12
+12
Ka whakahaeretia te whakahuahua (0 = pūmau, 1 = tino whakahuahua)
Te taumahatanga tohu whakawātea-whakahaere (nui ake = nui ake te whakahau-whakahaere)
E whakaahua ana i te kāhua reo i roto i te reo māori (ka whakamahia e te Pāpāho tēnei i te wāhi o ngā reo i whakaritea i mua)
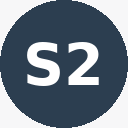
He pūāhua taupānga te taupānga taupānga: Ka whakamahia ngā tohu [S1] me [S2] hei tohu i ngā kaikōrero rerekē. Hei tauira: [S1] Hei hei! [S2] Hei, he pēhea koe?
StyleTTS 2, developed at Columbia University, achieves human-level text-to-speech for single-speaker synthesis by combining style diffusion with adversarial training guided by large speech language models. Its diffusion-based style modeling captures the full natural variation of human speech — subtle shifts in rhythm, emphasis, and tone — so output can rival real recordings. It is widely regarded as one of the most natural-sounding open single-speaker models, which makes it a strong choice for studio-quality narration and professional voiceover where polish matters more than cloning or multilingual range. StyleTTS 2 is English-focused and released under the permissive MIT license.
Pai mo: Studio-quality single-speaker synthesis, professional narration
MIT (code); pre-trained model requires telling listeners the speech is synthesized
Karaka
premium
Āhuatanga
medium
Whakakōrero reo
Kāore
reo
English
Kāri nui rawa
500
StyleTTS 2 ngā oro
Default
English
WhakawhiwhingaNeutral
StyleTTS 2 TTS - FAQ
It combines style diffusion with adversarial training using large speech language models. The diffusion-based style modeling captures the full range of human speech variation, producing output that can rival real recordings.
No. It is focused on producing the most natural single-speaker synthesis rather than cloning a specific voice. For cloning, use a model like Chatterbox or GPT-SoVITS.
Studio-quality single-speaker work — professional narration and voiceover — where naturalness and polish are the priority. It is English-focused and MIT-licensed.
E tāuru ana i tōna mairā hei haere tonu i te whakaputa kōrero mō te wāteatanga, hei whakaingoatanga rānei mō ngā pūāhua tāpiri 15,000.
Kāore he kupu whakarongo e hiahiatia ana — ka tukuna mai e tātau he pātahitanga ki te tautuhi i tētahi i muri ake nei.
Kua tae te tepe taumata wātea
Kua whakamahia e koe ōna pūāhua wātea 5,000 i ia rā. Whakatū i tētahi kāwanatanga wātea kia whiwhi ai ki ngā pūāhua tāpiri 15,000 tae atu ki ngā pūāhua wātea 10,000 i ia marama.